SpiderGate Blog
Architecture, engineering, and operational intelligence for production LLM systems.
All Articles
Your model list says yes. The provider says 404.
SpiderGate can now tell you which of your own subscriptions may serve a request. The surprising part is the field that says we permit it is not the field that says it works.
 Martin Shein
My own dashboard was making up numbers
SpiderGate's usage page showed a $2,000 budget, a Pro plan and a 1,000 RPM ceiling. No column in the database held any of them. The success rate came from HTTP status, so a call that returned nothing counted as a win. Here is what I deleted, the four-state split that replaced it, and the number I got wrong by 1,000x while fixing it.
Martin Shein
HTTP 200 is not the same as an answer
Some models return a well-formed 200 with an empty body, and you are billed for it anyway. I moved SpiderGate's check in front of the provider call: 166,096 requests since, no request refused that another model could have served, and the aliases that were burning tokens for zero characters now return an error you can act on.
Martin Shein
A model's capability list is not a capability test
I probed 70 models with a real tool call. 25 advertised tool support and failed. Here is what that costs an agent loop, and the boring fix.
Martin Shein
A prompt should be an object, not a paste buffer
A saved prompt in the SpiderGate Studio bundles the system prompt, model, settings and reference media under one name — reloadable in a click, callable from an agent by that name, and expanded server-side. Around it sits a workbench: projects that keep your conversations and generations, Fork and Merge across several models at once, and a trace on every run.
Martin Shein
Contribute an API key without ever showing it to me
A teammate has the Groq account, a client holds the OpenRouter billing, and nobody wants to paste a live secret into a chat window. The SpiderGate Vault takes a contributed key through an invite link, encrypts it, and shows me only a masked preview — while a shared pool with round-robin failover keeps requests flowing when one key rate-limits or dies.
Martin Shein
1,216 models, and an agent that keeps the catalog honest
The SpiderGate catalog tracks 1,216 models across 16 providers, and an agent refreshes the facts every day. 221 of them are scored across nine capability categories as a within-category percentile — with the benchmarks behind every score, and the coverage stated plainly.
Martin Shein
Your password manager can't tell you what that key is spending
A credential store holds the key and stops there. SpiderGate splits a provider key into three axes — how it arrived, how it bills, and which package it is on — so a flat-monthly coding plan meters against its own rolling window instead of a dollar figure that means nothing.
Martin Shein
Stop keeping a second vendor just for pictures and speech
SpiderGate now takes images, video, speech, transcription and embeddings on the same Bearer token as chat. 33 of the 81 media models in the catalogue are active today, each publishing the exact parameters it accepts so an agent never has to guess.
Martin Shein
A dead key shouldn't wait for you to notice
A pooled provider key that dies doesn't stop your agents — it quietly degrades them to a fallback while nobody gets paged. Here's how I made SpiderGate pull a failing key out of rotation by itself, tell apart a bad minute from a dead credential, and email the one person who can actually fix it.
Martin Shein

How AI Automation Agencies Save Money with SpiderGate BYOK
Discover how shifting to a BYOK model with SpiderGate can eliminate inference overhead and maximize profit margins for your AI agency.
 Eli Vostok
Evaluating Gateway Latency Overhead
Adding a hop in your LLM request path adds latency. But how much? We dive into the benchmarks.
Eli Vostok
Securing LLM API Keys at the Edge
Shipping API keys to the client is a disaster. Explore why you need a gateway to secure your LLM API keys at the edge.
Eli Vostok
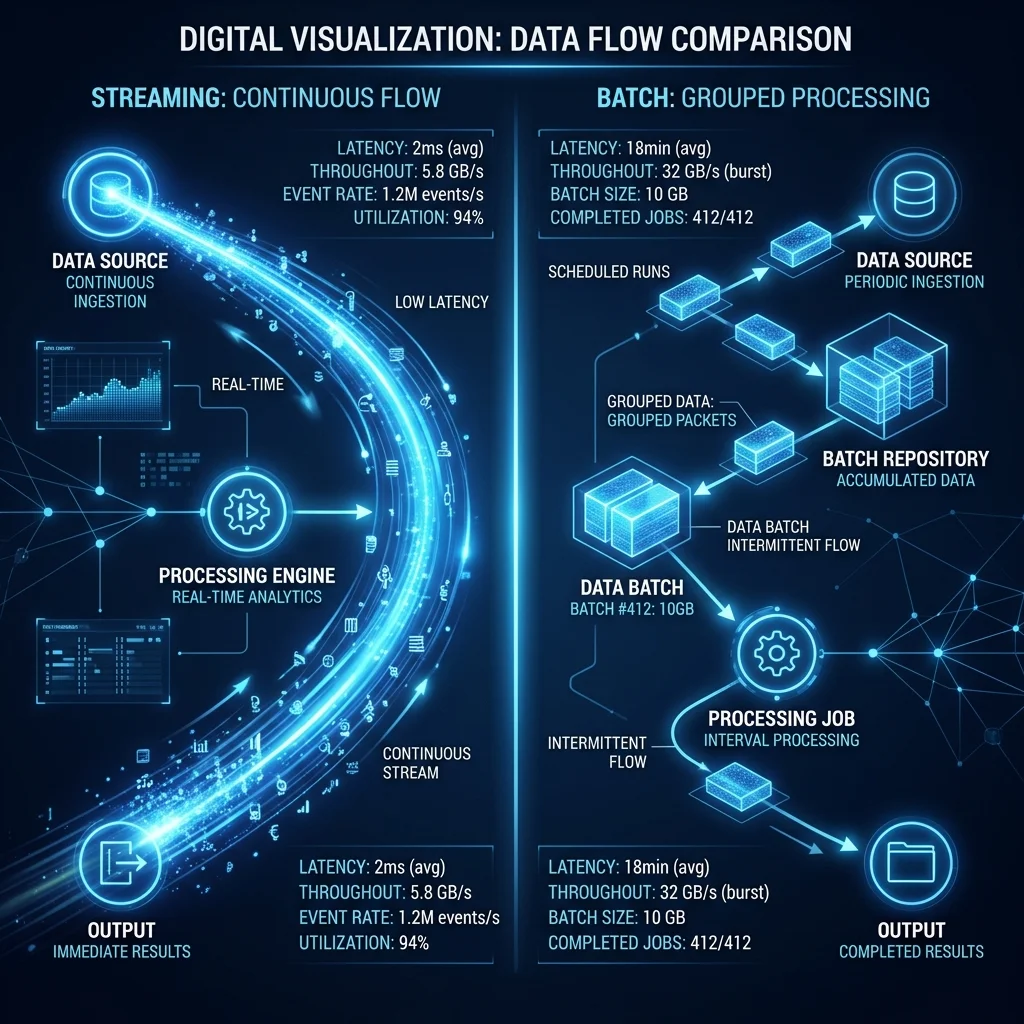
Streaming vs. Batch: Choosing the Right LLM Delivery Mode for Your Agents
Not every agent needs real-time streaming. SpiderGate's delivery mode system lets you choose between streaming, batch, and hybrid modes per agent — optimizing for cost, latency, or throughput.
Eli Vostok
Multi-Tenant Isolation: Running 50 Teams Through One Gateway Safely
When every team shares the same LLM gateway, data leakage isn't just a risk — it's an inevitability without proper isolation. Here's how SpiderGate enforces tenant boundaries at every layer.
 Dr. Mara Solaris
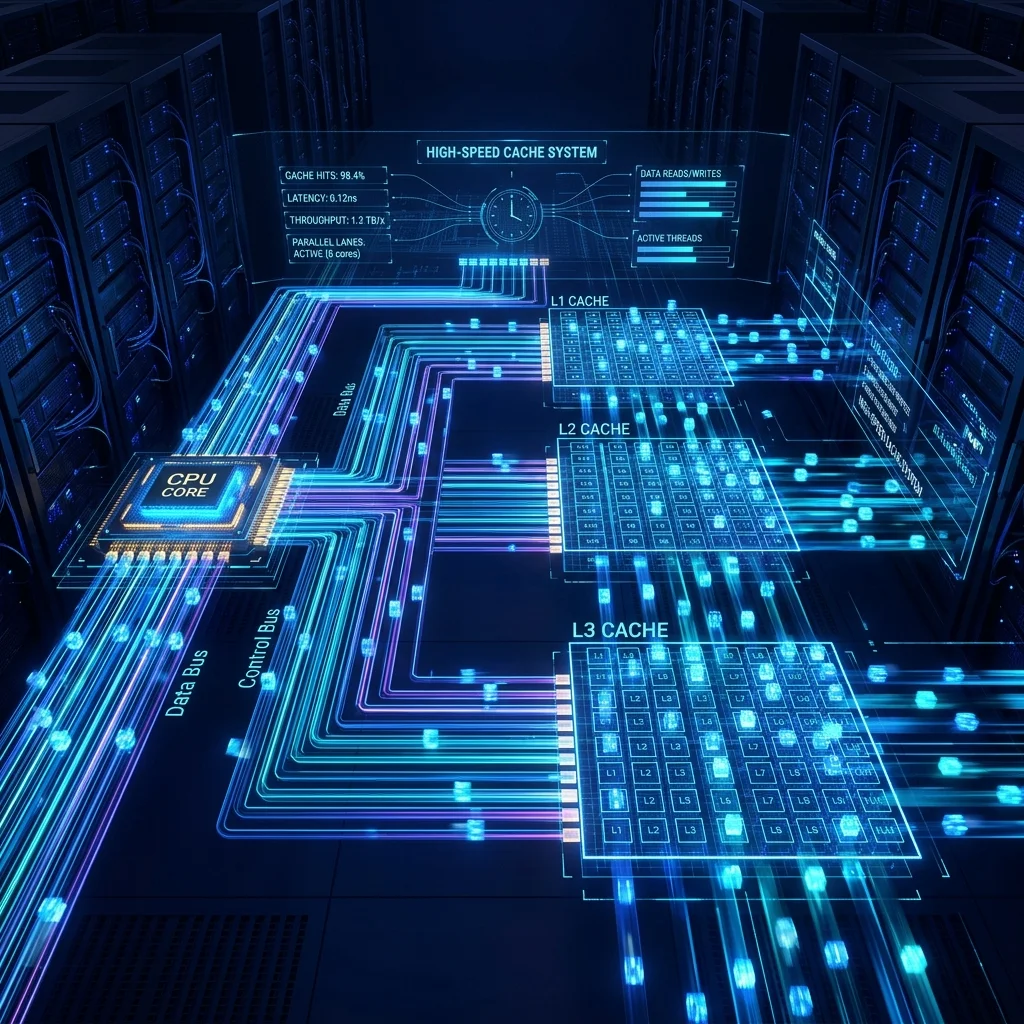
Prompt Caching at Scale: How SpiderGate Reduces Redundant LLM Calls by 40%
Your agents are asking the same questions hundreds of times per hour. SpiderGate's semantic prompt cache detects near-duplicate requests and serves cached responses, cutting costs and latency simultaneously.
Eli Vostok
Rate Limiting for AI Agents: Why Token Buckets Beat Simple Throttling
Simple rate limiting kills agent performance. SpiderGate's adaptive token bucket algorithm balances throughput with fair resource allocation across hundreds of concurrent agents.
Dr. Mara Solaris
Fallback Chains: Designing Resilient Multi-Provider LLM Pipelines
When your primary LLM provider goes down at 3 AM, your agents shouldn't stop working. SpiderGate's fallback chain system automatically routes to backup providers with zero application changes.
Eli Vostok
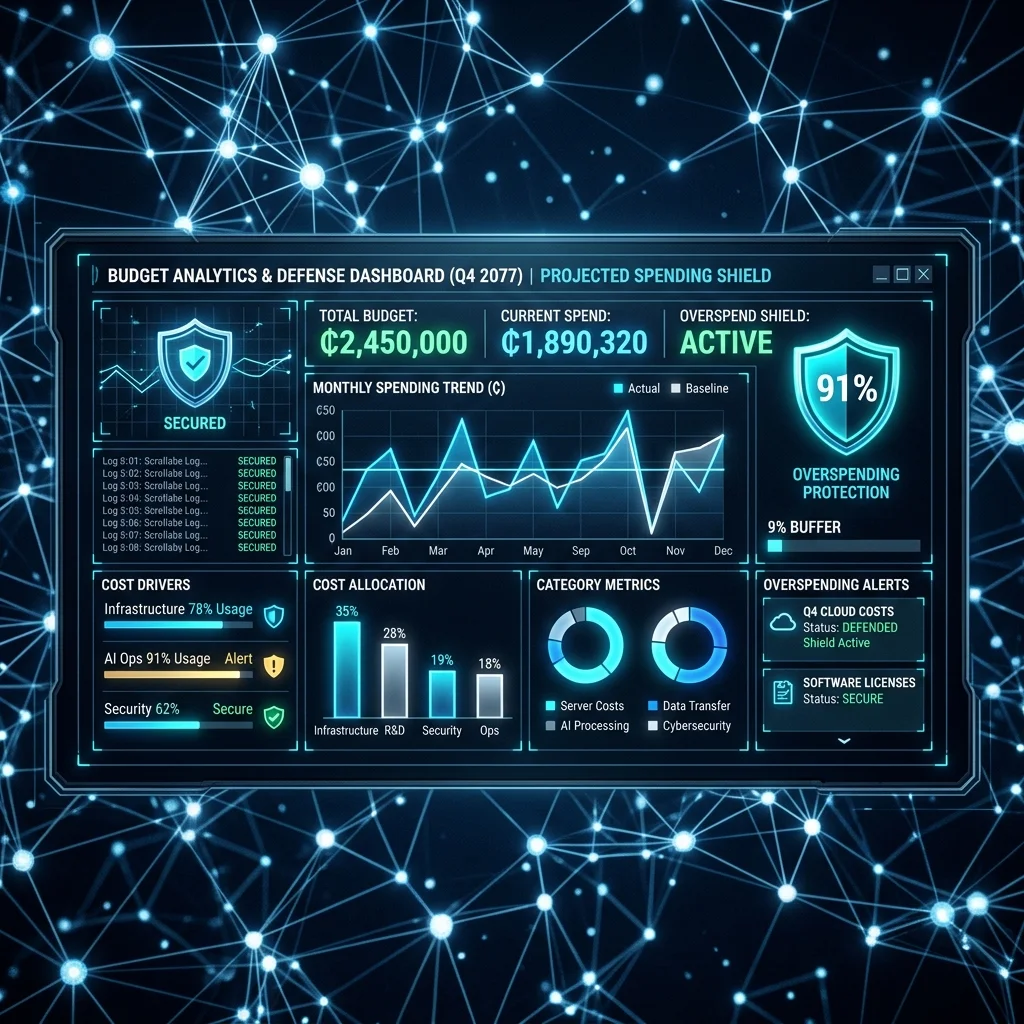
Budget Guardrails: How SpiderGate Prevents LLM Cost Overruns
One misconfigured agent can drain your entire monthly LLM budget in hours. SpiderGate's budget guardrail system enforces per-agent, per-model, and per-team spending limits in real time.
Dr. Mara Solaris
Your bill is per key. Your question is per agent.
Your provider bills you per API key. On a shared pool that tells you nothing about which agent spent it. Here is how SpiderGate's Traces view answers the question in the shape people actually ask it, plus the pool number I measured wrong the first time.
Martin Shein